Main menu
You are here
Planet GNOME

Diego Escalante Urrelo: LLM Policies: Progress At All Costs
GNOME and KDE have started to consider LLM policies, and we should talk about what this is really about.
KDE caught everyone's attention first by igniting a flame war with an LLM-friendly draft that ended up being deleted, causing a few bans, and having a bunch of people go full "Some of you may die, but that is a sacrifice I am willing to make". GNOME has not proposed anything official, but some teams (gnome-calendar, loupe, libadwaita, gnome-software, Circle, among others) already have strong policies in place, and there is now an informal draft to ban all LLM contributions to GNOME projects and infrastructure.
However I believe these discussions are not about nitpicking workflows but rather about the raison d'être, the reason to be, of FLOSS projects.
Communities Or CompletionismMy take is that there are currently two ways of thinking about why FLOSS exists, or should exist. So far, both sides have coexisted but the growing acceptance of LLMs into some developer workflows has disrupted the balance.
We can call one of these sides "collectivism". This frames FLOSS to be about accomplishing things together, enjoying the journey and bonds that big goals tend to create. The fun is the collective effort and challenge. Overcoming language and social barriers is part of the reward. "The journey is the destination", "FLOSS is the friends we made along the way", etc.
On the other side there is "completionism", where FLOSS is "just a product" and its only goal is to always be better, faster, safer. Any fun to be had is in individually solving technical problems and requirements. Social bonds may happen, but colleagues are more coworkers than community. This is a "100% allglitches alltricks" TAS speedrun. The "we are apolitical", "we only care about the code" view.
My assessment is that the collectivist framing finds FLOSS primarily a social exercise that rewards you with experiences, bonds, and ideas outside of your niche interests. Some times you even get good software as a bonus! The second framing sees FLOSS as a tool to scale the complexity of your individual computer interest, like graphics or security. FLOSS is a convenience compared to manually rebasing patches and forks all the time.
The problem we are facing is that LLMs have given the second group a lever to stop giving the collectivist framing any room. When the LLM can get you 80% of the way to your goal, there is no need to "waste" time in mentoring, discussion, or convincing others. The temptation compounds if you are considered an expert in your field. You can surely fill in the last 20%, right? Is anyone going to challenge not only the machine, but also the expert?
Progress At All CostsSince LLMs present themselves as neutral, and dispassionate, opposition to their output becomes opposition to objective progress: bug fixes, security hypotheticals, features. Progress is whatever the LLM, under my own careful eyes, says it is. Interactions with others become formalities, since the LLM is simply boosting my own, already expert and close to infallible, output. Right?
Unfortunately this "expert slop", where expert is a self-perceived title, carries a corporate framing that damages interactions. Others become, at best, fungible coworkers, and, at worst, annoying speed bumps in the race to 100% completion of any software interest the expert has. No more mentoring, debating, flame wars. "Progress" is the only goal. The line must go up.
There is more to say about how this machiavellian framing causes far more important harms and externalities, in the name of LLMs themselves, or apparent LLM-assisted progress. Think of any group and you will find out they have been handed part of the bill for these externalities:
- The people who will lose their homes, schools, lives, in the Global South because of El Niño 2027
- The towns destroyed by data center illegal and irresponsible practices
- The price of all consumer goods going through the roof because of financial speculation
- The pensioners who might lose their pension when the bubble finally pops.
These are the real costs in the "Progress At All Costs" that LLMs bring into FLOSS. These are the people who will pay the bill, behind the scenes and far from our screens, so that some big brain engineers can avoid reading documentation, writing boilerplate, learning unfamiliar code, or, worse, working with others.
FLOSS As Principled SoftwareAlmost ten years ago Allan Day described GNOME as Principled Software because of its commitment to always doing the right thing, in code or design, because it was the right thing and not because of ease, pressure, or hype. I believe this is why so many other FLOSS projects have always looked at GNOME for guidance on what good FLOSS should be. This discussion is just another opportunity to continue to meet this expectation.
Recent discussions have shared similar sentiments like reminding us that we do book clubs because we want to read and enjoy books, not to just discuss over summaries because it is "more productive". That when pressed to accelerate FLOSS, to make the line go up, we have to ask for whom do we want to be more productive, efficient, faster?. And that every decision is political and affect other people around you.
We already know that LLM productivity is not real, just a self perception, that LLMs are just a fairy tale to maintain tech stocks hypergrowth, by farming engineers for engagement, and the latest in a series of attacks to commoditize tech workers. Knowing all this, are we still going to play along with big tech's lies and exploitation? Or, are we going to make another principled stand?
GNOME did not need LLMs to produce 30 years of creative engineering, design, localization, inclusion, and collaboration that has been shared with people around the world. It does not need to throw away this incredible legacy simply because LLMs happen to farm our worst individualist impulses.
We came this far without compromising our principles, let's not start now.
Juan Pablo Ugarte: Casilda 1.6 Released!
I am very happy to announce a new version of Casilda!
A simple Wayland compositor widget for Gtk 4 originally created for Cambalache
This new version brings Drag&Drop and clipboard support / integration with the host compositor which means you can drag something from a host application and drop it on an application window embedded in a Casilda compositor widget and vice versa!
After a very rugged GUADEC presentation where I tried to show how to create simple Gtk application from slides made with Cambalache using a Casilda compositor to embed GNOME Builder and Cambalache itself I decided to fix all the issues I found so I could redo the presentation and upload it as a video.
This is a screenshot of the slider window, inside it there is a Casilda compositor (green line) used to embed a Cambalache instance which uses another CasildaCompositor (red line) to preview the UI.
Things that possi-bly could go wrong and did:
- Clipboard (Could not copy paste snippets)
- Keyboard numeric pad
- Keyboard modifiers in pointer events (I could not use Alt+Click to force create widgets)
- Example application connected to host compositor instead of Casilda widget
- Gnome Builder fullscreen window state broken
- Popover tooltips crash
After fixing all the bugs and keyboard support I started working on adding Clipboard integration with the host.
Clipboard supportIntegrating the clipboard between Casilda and Gtk was fairly easy since all I needs to be done is copy all the clipboard data provided by wlroots wlr_seat::request_set_selection event to GdkClipboard and call wlr_seat_set_selection() on GdkClipboard changed signal.
Wlroots client to GtkIn other to do this I created a new GdkContentProvider that uses a wlr_data_source as the source of the data and set the provider as the content of the clipboard with gdk_clipboard_set_content().
Internally when a clients wants to get data from the clipboard the new provider creates a unix pipe to read data from wlroots by writing to the pipe with wlr_data_source_send() and reading form the other end using g_output_stream_splice_async().
Gtk to wlroots to clientTo go in the other direction I created a new wlr_data_source that uses a GdkClipboard as source and set selection with wlr_seat_set_selection()
Internally gdk_clipboard_read_async() is called to initiate the data read when wlr_data_source send() method is invoked to send the data to the client.
Drag & Drop supportIntegrating D&D was not as easy as the clipboard. Setting it up to work within Casilda is easy enough other than wiring up some events all I had to do was draw the drag icon surface.
The first thing I did after getting the drag surface was draw it at the pointer coordinates which produced blurry results since pointer coordinates are fractional which means they do not always align with the pixel grid.
That was all nice and good but now I needed to start integrating the drag with Gtk (host compositor) so right after calling wlr_seat_start_pointer_drag() I created a GdkDrag with gdk_drag_begin() and used gtk_drag_icon_set_from_paintable() to set the drag icon and I noticed it was still blurry!!!
After a minute of confusion I realized that Gnome Shell (mutter) must be making the same mistake I did before so I decided to see if I could fix it!
Thanks to Michel Dänzer for guiding me and reviewing my MR, Gnome Shell 51 should have sharp drag icons!
Now back to integrating DnD with the host compositor.
These are all the different use cases that are needed to make D&D work transparently across host and guest compositors:
- Casilda client to Casilda client
- Casilda client to Host client
- Host client to Casilda client
Of course wlroots only contemplates the first use case, the other two cases are specific to Casilda.
Casilda to HostSo far we can detect when a client start a drag, let wlroot handle it and create a GdkDrag to let Gtk initiate another drag at the host level.
This means that when a client embedded in a CasildaCompositor initiates a drag there are two simultaneous drags at the same time, in the guest and host compositors. Keep in mind Casilda always delegates drag icon rendering to the host compositor.
During normal operation Casilda gets events from an event controller, but while on a drag operation events are not sent to the client at least not in the normal way, for that you can use a GtkDropTargetAsync and connect to the various signals for example I use drag-motion to forward events to the client.
Host to CasildaWhen a Drag is initiated in the host compositor Casilda reuses the GtkDropTargetAsync created to track motion events and connects to drag-enter signal to create a proxy drag source in wlroots and synthesize a button release event on GtkDropTargetAsync::drop to trigger the drop on the guest side.
Here is a screencast off all the different use cases in action.
As you can imagine getting all this to work together correctly is not trivial and I expect to be subtle bugs in different corner cases so please if you find one of those file a bug and include a screencast if possible.
Release Notes- Add DnD and clipboard support
- Add support xdg_foreign protocol
- Fix modifiers in pointer button press events
- Add keyboard Caps/Num/Scroll Lock support
- Fix popup of popup crash
- Fix maximized/fullscreen state handling
- Fix modifiers flags creation (Evgenii Danilin)
- Drop cursor surface listeners when the surface is destroyed (Evgenii Danilin)
- Close dup’d plane FDs when a dmabuf import fails (Evgenii Danilin)
- Advertise a valid output scale to avoid a scale-0 assert (Evgenii Danilin)
- Unref the wayland GSource (Evgenii Danilin)
- Meson config cleanup (Val Packett)
- Use gtk api for snapping to device pixel grid
- #20 “SIGSEGV in server_request_acvtivate”
Source code lives on GNOME gitlab here
git clone https://gitlab.gnome.org/jpu/casilda.git Matrix channelHave any question? come chat with us at #cambalache:gnome.org
MastodonFollow me in Mastodon @xjuan to get news related to Casilda and Cambalache development.
Happy coding!
Jordan Petridis: The GNOME LLM Policy That I Want
KDE is on the news because of a controversial proposal to define an official “AI” (LLM) policy. Other projects have tried their hand at similar policies and stances but, in my opinion, they miss the mark about the goal of such initiatives. I think that the point of these statements is shaping social norms and not micro-managing developer workflows. They should be about signalling what kind of behavior we want, and what kind we reject.
This proposal does not go into detail about the many problems that LLM have caused to society, workers, the environment. It goes without saying that all these ills are fundamentally opposed to the humanist spirit of GNOME.
With all that in mind, here is what I personally think a GNOME LLM policy could be:
A GNOME Project LLM Policy The GNOME Project prioritizes the social and human aspects of collective software creation. Therefore: 1. LLMs ("AI") can not be used to create or modify code submitted to GNOME, or hosted on GNOME infrastructure. You might be asked to prove your code meets this requirement. You might be banned for trying to circumvent this policy. Example Guidelines for ContributorsThese are just a draft of the kind of criteria one could use to evaluate if a submission fits the policy.
- You must be able to personally reason and explain your changes
- You must be able to demonstrate knowledge of the problem space you are working on
- You must solve the underlying issue, not just its symptoms
- You must respect the time of fellow contributors
- You must not impersonate yourself through chatbots, agents, or other automated systems
GNOME is not just software that happens to ship every six months. That is just a delusion we have been holding up for the last 30 years to keep our loose group of colleagues, friends, and acquaintances, together.
GNOME exists as a collective that find joy in reaching beyond our individual limitations to achieve something bigger. These people, this joy, are the whole point of the project. Contributors are not payroll, a liability, that we hope to downsize next quarter.
“Come do free labor for a handful of corporations by reviewing chatbot output in your free time” is not an attractive proposition to young talented people in 2026. If we want GNOME to continue we need to create an attractive and inviting social space where people are valued as people.
Just like the Foundation is moving to individual donations to stop depending on just a handful of companies, we need to look for the next 100 people that will donate a tiny bit of their time, instead of hoping that corporations will keep 10 overworked engineers on staff. We already have seen how companies will happily abandon a whole chunk of GNOME on a whim.
GNOME is not just software, and it should protect the social and human aspects that make it special. Our success metric is the community and social bonds we create. In the most literal sense GNOME is about the journey and the friends we make along the way.
Free Palestine.
FAQ How do you enforce this?You can not. People will still send LLM generated code. This policy makes it explicit that we do not welcome these careless submissions. We have a Code of Conduct that is 80% about telling other people what our values are, and 20% about handling unwanted behavior (“enforcing”). This is similar.
What if people simply lie about not using LLMs?This is the same problem as authorship, in the copyright sense. Whenever we receive new code we have to assume that “beyond a reasonable doubt” said code has been authored by the person contributing it. We make our best guess. The attached guidelines are a suggestion to make these new guesses.
Ok. But what if people are really good at lying?This policy is about the majority that will not even try to lie. See previous questions.
Hylke Bons: Bobby 51
With the imminent release of GNOME 51, I realised I hadn’t released an update to Bobby in a few months.
The long tail of crash reports after a release just doesn’t seem to happen anymore when working with Rust. It’s just done and I moved on to other things.
Bobby follows the GNOME version number scheme for convenience, but I did not want to let a major version bump go by without at least one new useful feature. So I’ve added search.
It uses case-insensitive fuzzy matching to filter out rows and highlight cells using the system accent colour as you type.
Simple yet effective!
FutureThere are now two big features left that I want to implement:
- Encrypted file support
- Updating values in place
I’m not sure which one to work on in the next cycle, so let me know in this poll on the Fediverse which is most useful to you.
Happy equinox and don’t forget to sanitise your database inputs!
Carlos Garcia Campos: Skia compositor for WPE WebKit and WebKitGTK
WPE WebKit and WebKitGTK 2.54 have been released with a bunch of improvements and new APIs as usual, but there’s one point that kept the Igalia WebKit graphics team busy for the whole cycle: the new Skia-based compositor. The replacement of Cairo with Skia for content rendering has been a success and it’s already well integrated and optimized. We thought we could try to use Skia for the composition too and replace TextureMapper with Skia. TextureMapper was introduced in 2010 for the Qt port and later adopted by other ports. It uses the OpenGL ES API and maintains a collection of shader programs to paint different content. Nowadays TextureMapper is mostly the same code and shader programs, and it’s unmaintained and missing features. However, the performance was good and it has served us really well all these years. So, this time the goal was not to get better results in benchmarks, but to modernize the implementation, reduce the amount of code to maintain ourselves (like all shader programs) and make it easier to implement the missing features and fix existing bugs. This post is a summary of all the work we have done this cycle to implement the new Skia compositor.
SkiaCompositingLayerThe first step was adding an SkiaCompositingLayer class to replace TextureMapperLayer and adapt all the code to use one or the other depending on an environment variable. The initial implementation was based on the TextureMapper one for the things that are common like iterating the layer tree, computing transformations, etc. The way layers produced their contents didn’t change, so we were receiving textures for tiled content, video buffers, WebGL, accelerated 2D canvas, etc. SkiaCompositingLayer created a Ganesh Skia surface to draw those textures using SkCanvas::drawImageRect(). This initial implementation was enough to run the default MotionMark test suite, since it doesn’t use other composition features. Even though performance was not the goal, we had to make sure we didn’t regress. This initial implementation was neutral in MotionMark. We needed tests to implement those features and measure performance at the same time, so we decided to add a new set of tests to MotionMark, just extending the existing tests to require composition, which makes sure that filters, masks, path clipping, transformations, etc. were done by the compositor.
FiltersWe first tried implementing filters using an intermediate surface like TextureMapper does. It worked, but the MotionMark score in the filters test was much worse. We realized that with Skia we could implement most of the filters without using an intermediate surface. All filter types except blur and drop shadow can be simplified to an SkColorFilter with SkImageFilter::asAColorFilter() which can be implemented without an intermediate surface, just by setting the color filter in the SkPaint we pass to SkCanvas::drawImageRect(). This not only fixed the performance regression, but also gave better results than TextureMapper, which always needs an intermediate surface.
MasksThere are two different kinds of masks: image mask, where the source mask is an image already, and clip path, where the mask is represented by a path to be clipped. In TextureMapper both are implemented the same way using intermediate surfaces. The mask is painted into a surface and then the masked layer creates an intermediate surface where its contents are first painted and then the mask contents on top using DstIn blend mode. Skia has APIs that allowed us to implement both cases in a much simpler and more efficient way. In the case of image masks, where we already have an image, we paint the mask contents once and keep it cached, and then the masked layer creates an SkShader for the image mask that is passed to SkCanvas::clipShader() without having to paint into an intermediate surface. Clip path masks are even easier, because we can just take the path we get and build an SkPath we can pass to SkCanvas::clipPath(), without having to paint the mask as an image at all or use any other intermediate surface. Once again, masks were not only easier to implement but they ended up being more performant too.
MotionMark composition suite, WPE with GPU rendering on a Raspberry Pi 4, comparing TextureMapper (312400@main) with the Skia compositor (313600@main). TextureMapper never implemented blend modes, so its high score on bouncing blend circles is the score for not doing the work. 3D contexts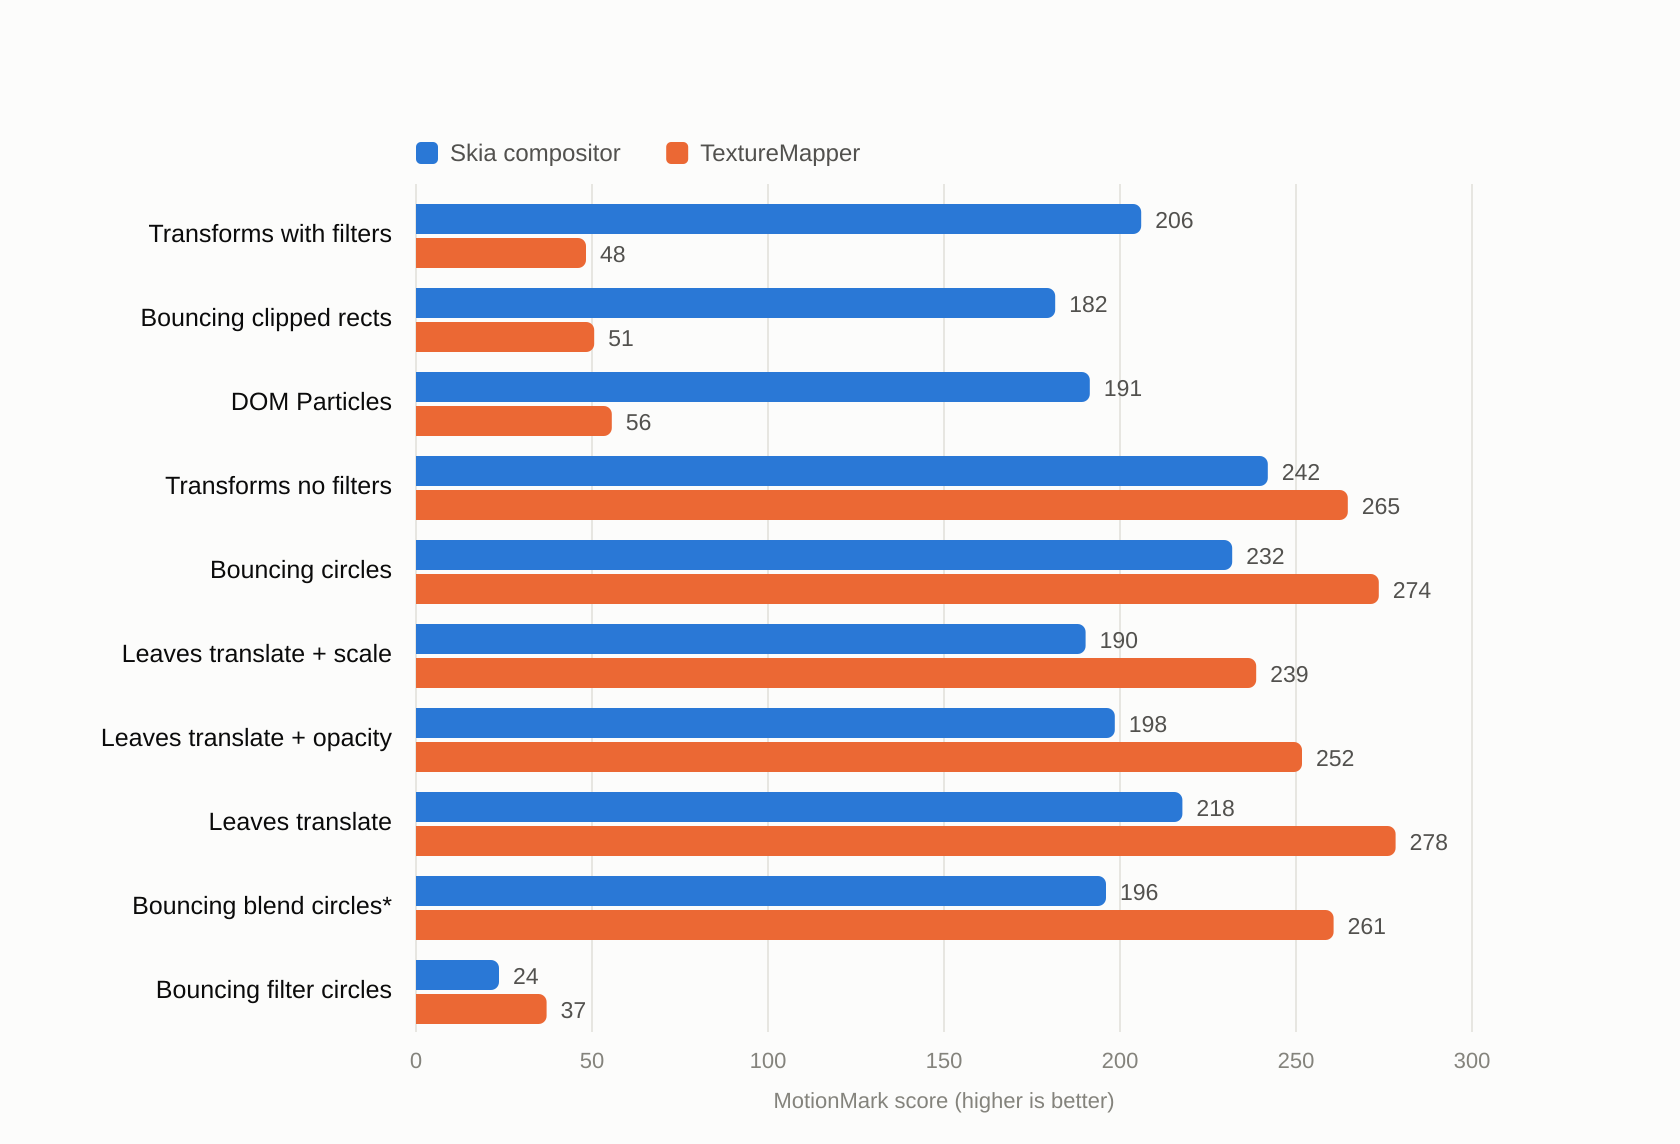
The implementation of 3D layer contexts is fairly independent of TextureMapper and OpenGL, so we could just take it almost as it was, using SkPath to build the clips and a few other adaptations. We could also fix existing bugs like the z-ordering that has always been broken in TextureMapper.
The same page rendered by TextureMapper (left) and by the Skia compositor (right), WPE on the same build. The red box intersects the rotated green plane. TextureMapper draws the box flat against the plane, so the intersection is lost; the Skia compositor splits it, drawing the part in front of the plane and hiding the part behind it. Blend modes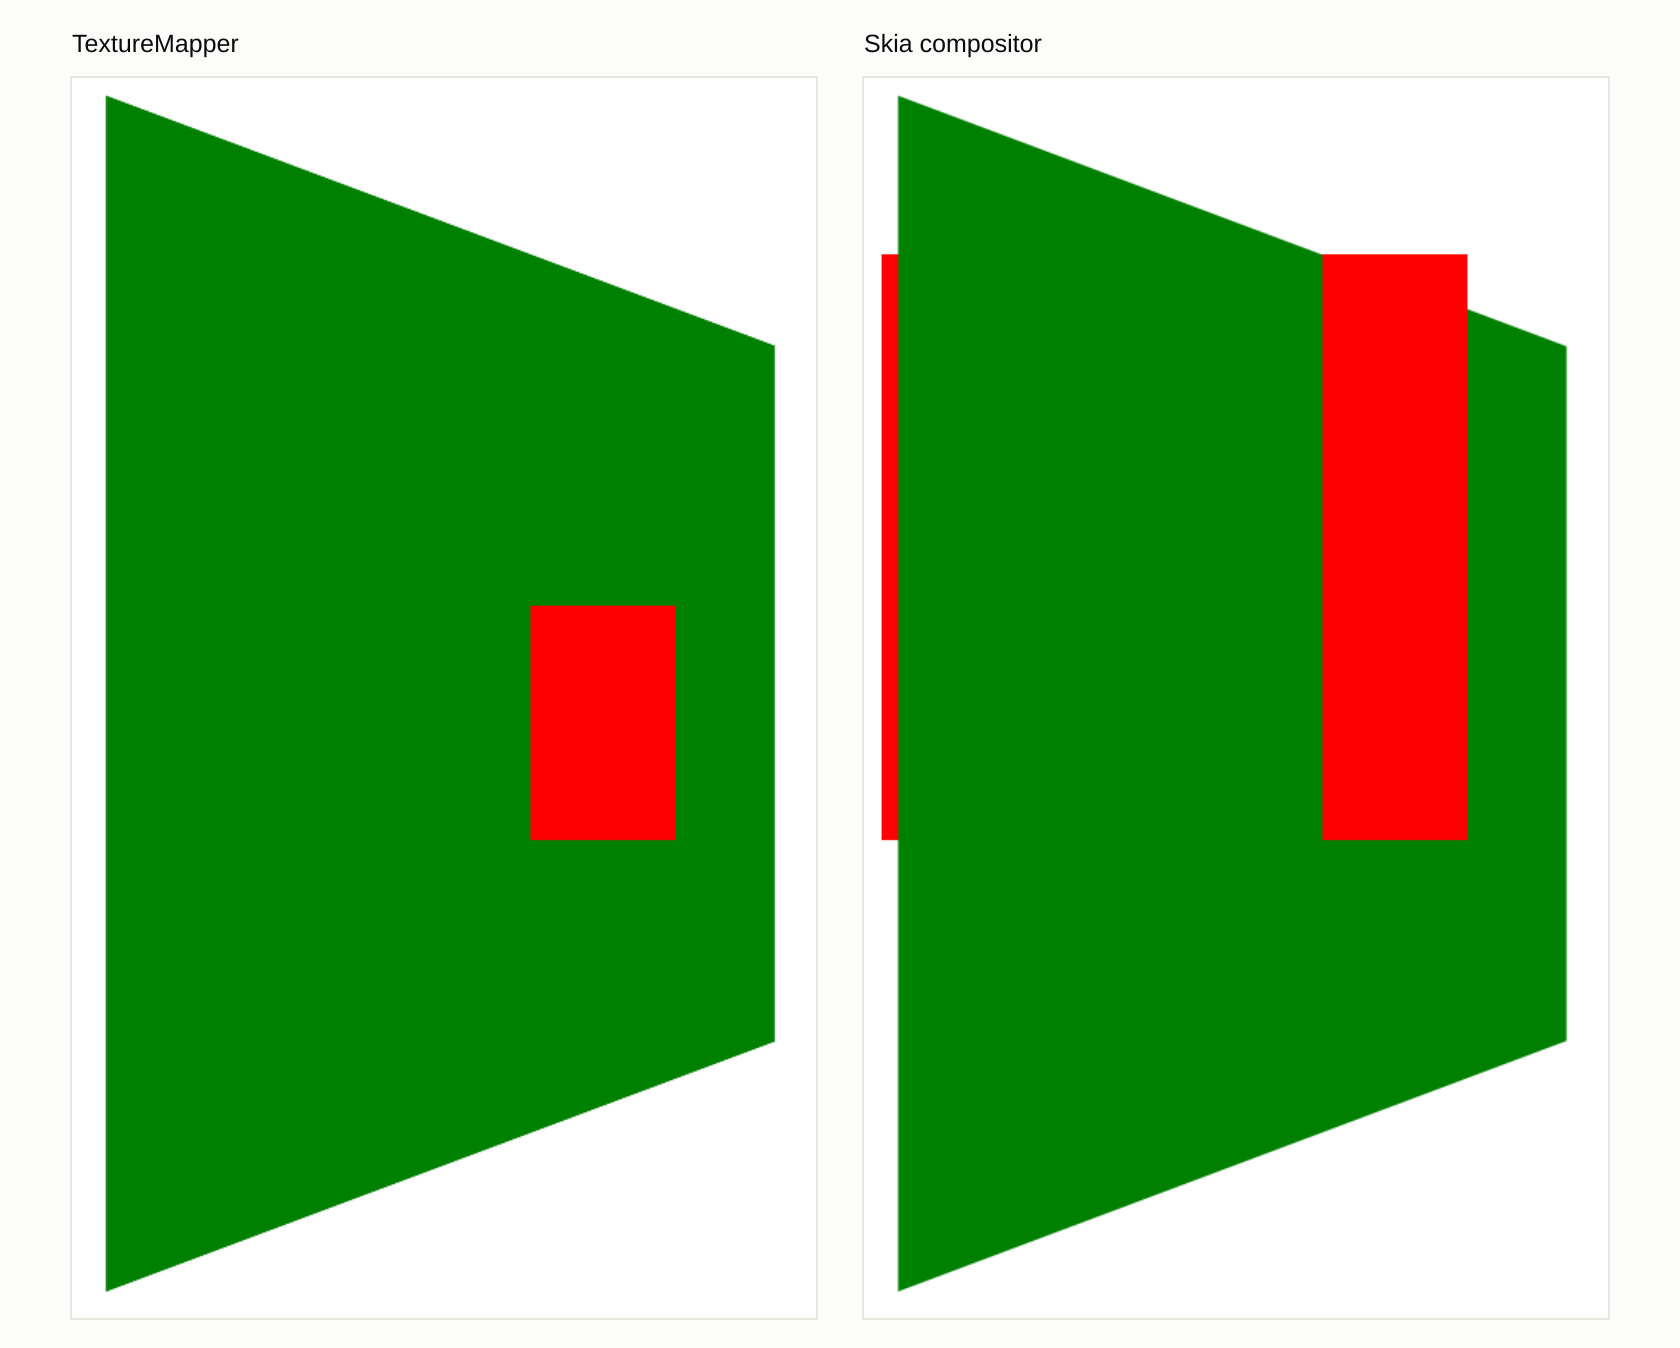
TextureMapper never supported blend modes and they were easy to implement with Skia just using the SkPaint property for it. This made several layout tests start passing.
Batched paintingAfter implementing all the features we were at a point in which we had the same or better performance in all tests except for three MotionMark compositing tests that were giving much worse results. Those tests use small layers and give a high result which means we end up adding a lot of layers to the scene before we start skipping frames. The root cause was the large number of layers filling the command queue of Ganesh. Skia Ganesh queues the GL drawing operations instead of sending them to the GPU right away. When the surface is flushed for whatever reason, the queued GL drawing operations are then processed and sent to the GPU. This allows Skia to apply nice optimizations like merging several tasks and reducing the amount of draw operations we end up sending to the GPU. In those tests where a lot of layers are created and painted to the compositor Skia surface the internal command queue ends up being huge too. Processing and analyzing such a long queue to optimize what we send to the GPU required more CPU work than what we save by optimizing the GL draw operations. Skia provides an API that allows us to do the batching ourselves. Since the compositor already has information to decide what operations could be merged together, we could reduce the internal queue size in many cases. We can merge SkCanvas::drawImageRect() operations as long as they share the same color filter, blend modes and sampling options. In the best case scenario we could reduce the whole internal queue to just one operation. This time the change improved the results of those tests getting them to about 93% of the TextureMapper score, but still a bit behind.
Promise imagesThe Skia Ganesh backend requires that an SkImage backed by a texture is created for the current thread GrDirectContext, even if it’s borrowing an existing texture. In WebKit all textures are created with a sharing GL context so that they can be accessed and destroyed from different threads with the same sharing GL context. So, for a layer whose content is an image we had to create a texture in the compositing thread to upload the pixels if the image was not accelerated, or for accelerated images get the texture identifier of the image, and then create another SkImage from the compositing thread borrowing the texture for the current GrDirectContext. The Skia Ganesh backend provides an API to create promise images, which can be created from any thread but targeting a specific thread, providing a fulfill callback that will be called on the target thread when the SkImage is first used to retrieve the wrapped texture. This way we can create the SkImage from the main thread for the compositing thread without using OpenGL at creation time. For non-accelerated images we realized we don’t need to manually create the texture and upload the pixels in the compositor, we can just pass the unaccelerated SkImage to the compositor SkCanvas and Skia will handle it internally much more efficiently than we did. And this change improved those compositing tests much further than we expected. The reason turned out to be the batching from the previous section: Skia merges the entries of an image set by comparing texture proxy pointers, and until now we were wrapping the texture in a new SkImage on every frame for every layer, so hundreds of layers drawing the very same image produced hundreds of different proxies that Skia could not merge. Passing the same SkImage every time collapses all of them into a single draw operation, which is the best case we described above. With batched painting and promise images together we could beat TextureMapper significantly.
MotionMark composition suite, leaves subtests, WPE with GPU rendering. Score per revision; higher is better. The same two steps appear with CPU rendering. Deferred Display Lists (DDL)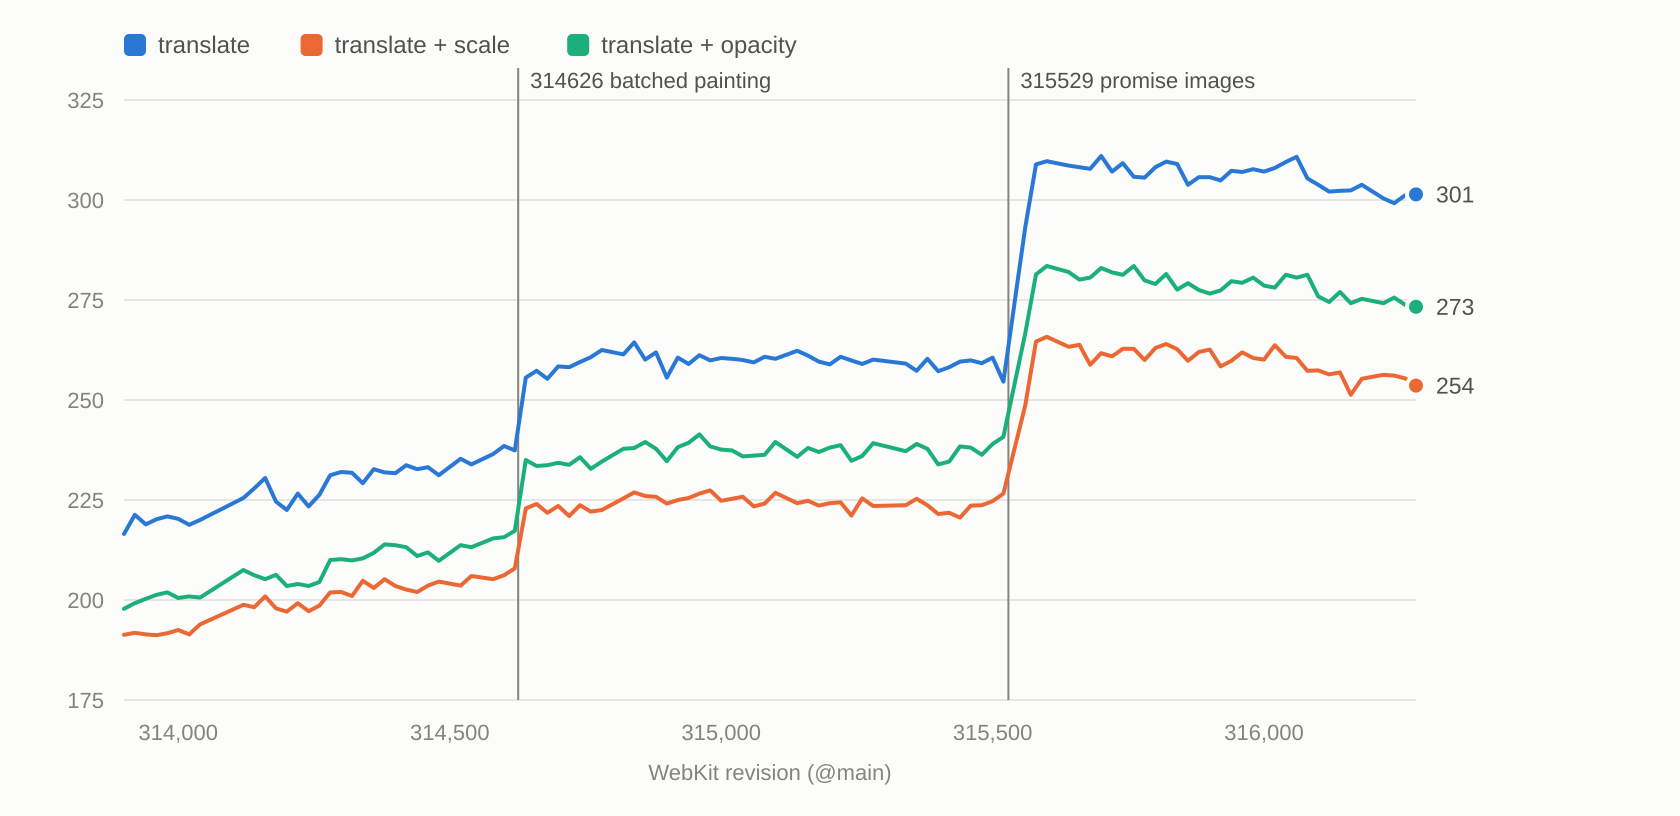
When we switched to Skia for painting, we kept the threaded rendering model, just using a separate smaller queue for GPU rendering workers. The GPU workers created their own GrDirectContext to paint the layer tiles. The resulting textures were re-wrapped in the compositing thread for the compositor GrDirectContext using fences for the proper synchronization. We knew this was not the recommended way to use Skia Ganesh from multiple threads, but with TextureMapper we had no other option. However, with the Skia compositor we can do it the recommended way by using a single GrDirectContext in the compositing thread and use Deferred Display Lists (DDL) and promise images to paint the tiles. With DDL, GPU workers no longer use GL at all and they don’t need a GrDirectContext, they paint tiles into a display list that records the GL drawing operations, but without touching GL. For image drawing operations recorded into the DDL, promise images are used too. Since this is now all CPU work we can remove the smaller GPU worker queue and use a single queue with more workers. The compositor replays the DDL into an SkSurface that is then passed to the compositor SkCanvas.
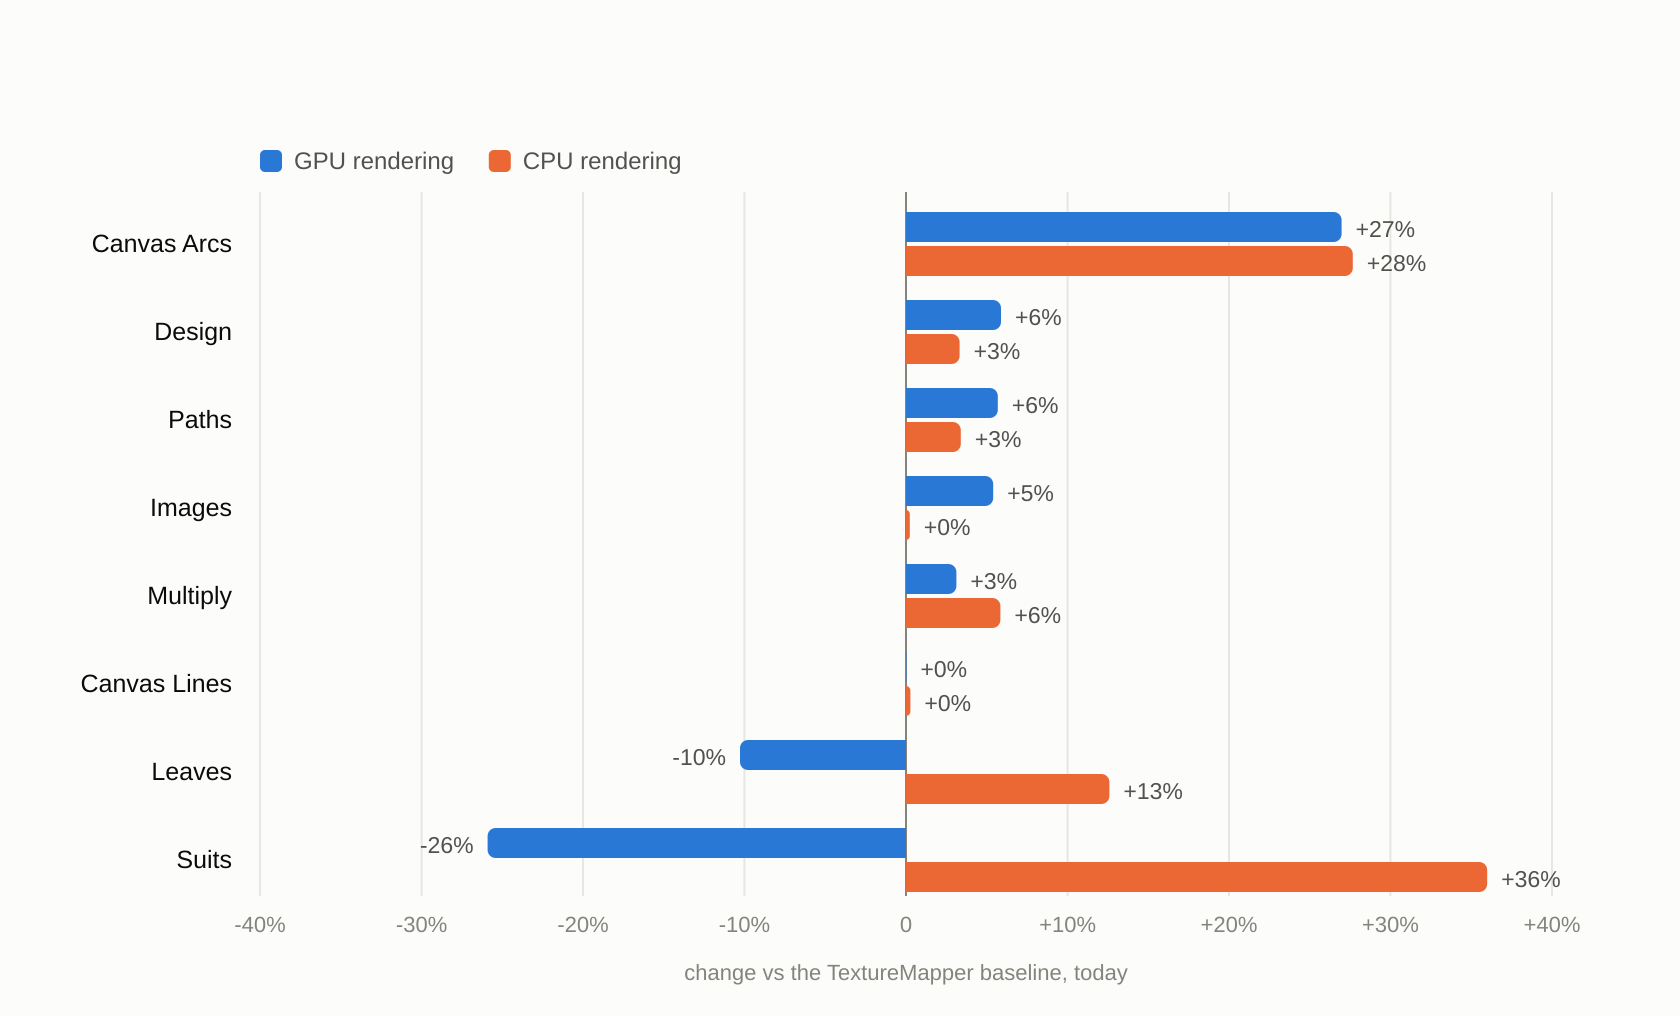
This change fixed rendering glitches on Android and was performance neutral for the whole composition suite and for most of the MotionMark tests, but in MotionMark 1.3 at 15fps it cost 29% in Suits and 14% in Leaves, while improving Images by 9%. Correctness and the other benefits of DDL made us accept those regressions.
MotionMark 1.3 at 15fps, suits subtest, WPE with GPU rendering on a Raspberry Pi 4. Shaded regions are where deferred display lists were enabled by default. CPU rendering moves less than 1% at all three switches, since it has no GPU worker threads for DDL to change. Damage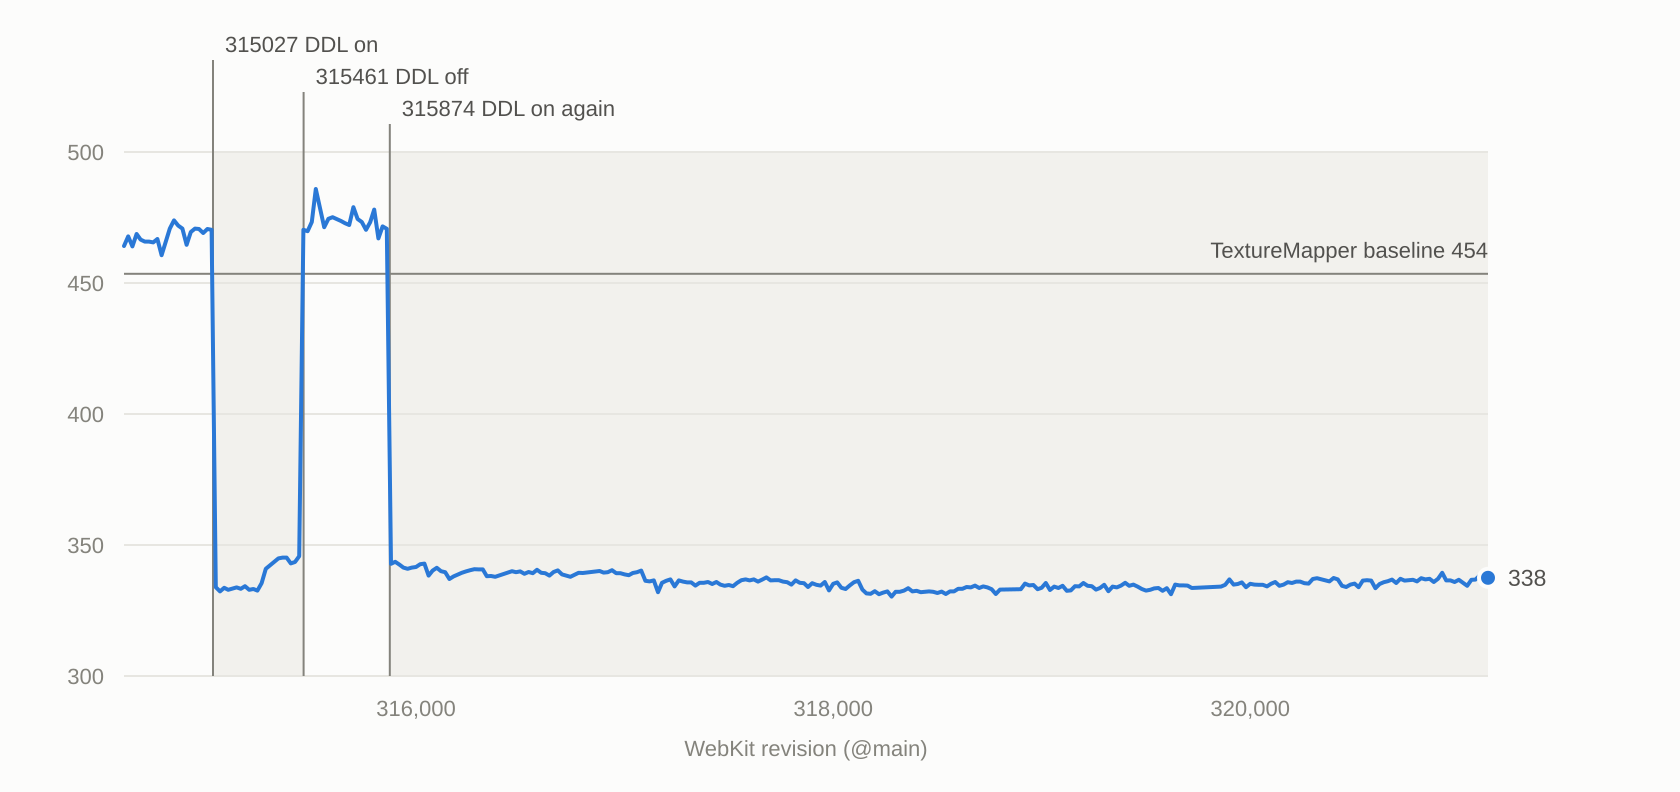
TextureMapper already supported using damage information to optimize the painting while compositing, but it has always been disabled at run time because there were issues we never managed to fix. With the Skia compositor we decided to start from scratch and properly handle the damage information while compositing to render only the parts of the frame that actually changed. I’m not going to go into detail here because Nikolas Zimmermann has written an amazing blog post about it with all the details.
Current situationThe Skia compositor is finished and enabled by default in 2.54. Even though it was not the main goal, it performs better than TextureMapper in most of the benchmarks we run: the composition suite we added is 45% faster, and MotionMark 1.3.1 is 35% faster. The exception is MotionMark 1.3 at 15fps with GPU rendering, which comes out flat, because the Suits and Leaves tests are still about 26% and 10% behind due to the deferred display lists trade-off described above.
We are already working on fixing existing issues in composition that we never fixed in TextureMapper. In the main branch TextureMapper is now disabled by default at build time, and support will be removed soon for the GTK and WPE ports. In 2.54 it’s still a run-time decision so if you find any issue with 2.54, you can check if it’s a Skia compositor regression by trying TextureMapper with WEBKIT_USE_SKIA_FOR_COMPOSITION=0 environment variable.
Overall (geometric mean) score, WPE on a Raspberry Pi 4: 320000@main and later against the TextureMapper baseline at 312400-313296@main. Bars start at the baseline. Part of the gain in the MotionMark suites is Skia rendering work rather than the compositor. WPE on a Raspberry Pi 4, change from the TextureMapper baseline (312400-313296@main) to 320000@main and later. Suits and leaves are the deferred display lists trade-off, not the compositor switch, which was neutral in this suite. Future plans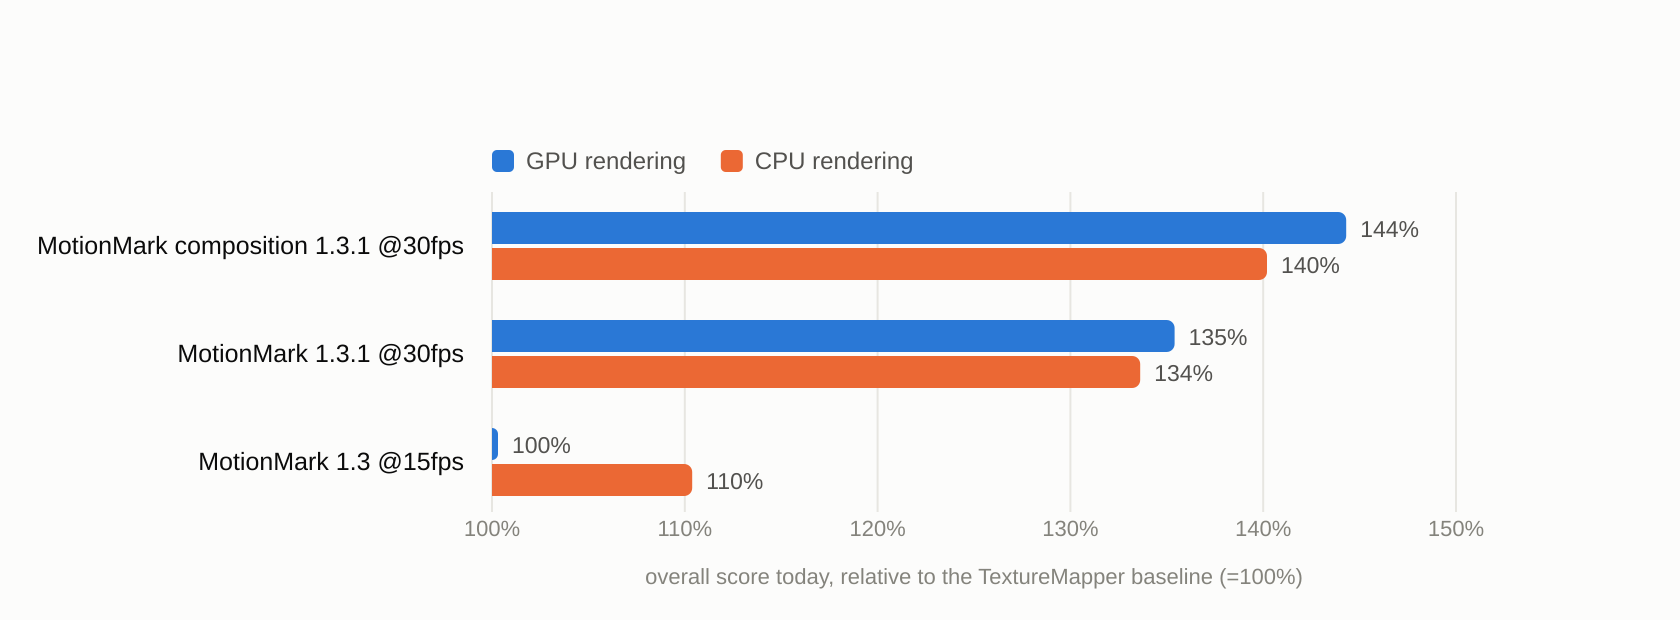
We are already working on further improvements like using promise images for all external textures we have to pass to the compositor. We will explore the possibility of using Vulkan with the Ganesh backend instead of GL and eventually try the new Graphite backend. And of course we will continue fixing any existing issues related to the compositor.
Jakub Steiner: Stolen!
Bombarded by the deception and lies of the AI industry I chose to sample boy Amodei for the ironic outrage about Chinese companies stealing their dataset. Thus the tune title.
Usually I barely manage to finish up my weekly beats track on a Sunday night. This week I've somehow had some extra time to sink into polishing an actual full track on the Dirtywave M8. Built around the bassline where I've mimicked the approach used on the Analog 4 of fading in a modulated filter and volume pulse over time using slight different tools (the M8 has 4 LFOs and ability to modulate a modulator).
Michael Meeks: 2026-09-19 Saturday
- Pleased by the somewhat quirky conference venue, good to meet lots of old friends & catch up with them; to hand out large numbers of beavers, and to hear various interesting updates on what is going on in Nextcloud the software.
- Gave a very compressed Lighting Talk for five minutes on what we've improved over the last year:
- Enjoyed talking with lots of smart people until late at night with a party, dancing & more - nice. Back to the hotel, and out for a Kebap with Jan, Andy & Tim.